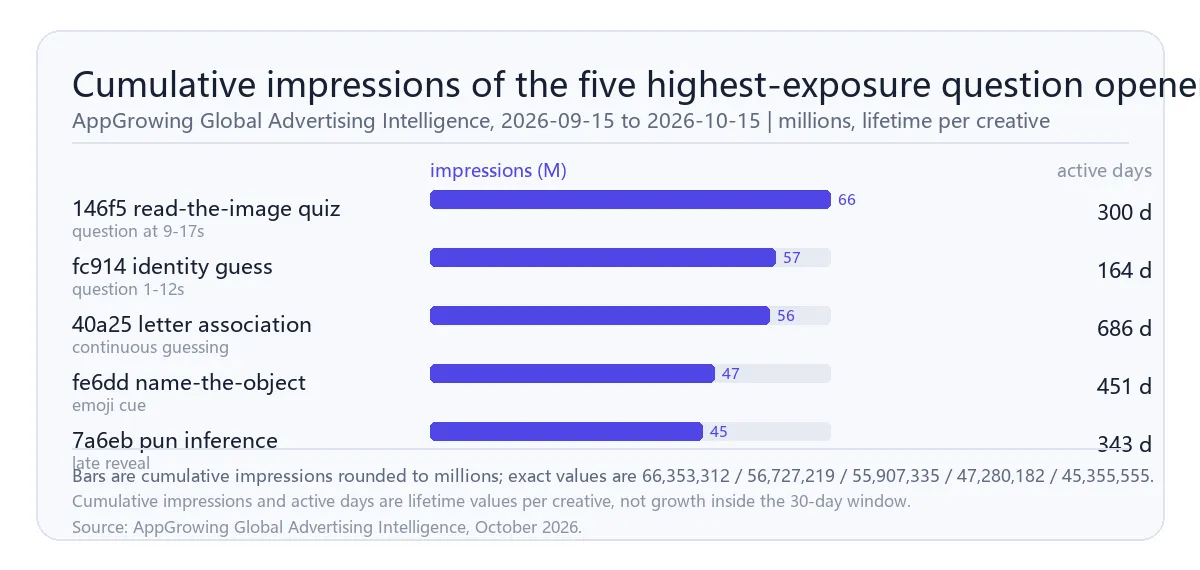
To build a question-style opening, treat the question as the targeting device and the option set as the retention device. In 10 AppGrowing Global creatives with explicit opening-question evidence from 2026-09-15 to 2026-10-15, the five highest-exposure rows run from 45,355,555 to 66,353,312 cumulative impressions, each posing its question inside the first 12 seconds and holding the correct answer until after the 20-second mark.
Why does a question buy the first three seconds?
Because viewers answer before the ad does. The highest row, Creative 146f5, opens a read-the-image name-it quiz at 66,353,312 cumulative impressions, 300 active days and 86 linked ad creatives, with the question landing between 9 and 17 seconds and the tap interaction between 18 and 27 seconds. Creative fc914 poses an identity guess, "who is this?", at 56,727,219 impressions and 164 active days, holding the question for the first 12 seconds. Creative fe6dd asks "what food is this?" with an emoji cue at 47,280,182 impressions and 451 active days. Creative 40a25 runs a letter and phonetic association at 55,907,335 impressions, 686 active days and 188 linked ad creatives, spending nearly its first 25 seconds on continuous guessing and self-correction. Creative 7a6eb pushes the pun inference furthest at 45,355,555 impressions and 343 active days, delaying the reveal so late that the punchline carries the answer.
Which question formats show up in the sample?
Three families. The first is street or duo identification: two real people, one holding the device, a large centred question, and no context required, so the viewer answers automatically. The second is image-association deduction, where an absurd or collaged image invites a reading based on sound and meaning at once. The third is counted spot-the-difference, which quantifies the task inside the first second and drives completion with a visible counter such as found 7 of 15. The three families differ in the kind of effort they ask for: naming an object, resolving a pun, or completing a count.
How should the option set be built?
The sample builds options so that the viewer can vote immediately. Word buttons and wooden letter tiles are laid out in a three-tier stack, centre-aligned, with a finger-touch prompt and a high-contrast outline on the candidate. Some rows add a hint button inside gameplay, and one row treats letter fragments themselves as the candidates while a personified letter mascot sits opposite a live-action couple. The functional goal is the same in each case: turn curiosity into a bet the viewer wants to settle, and make the tap cheap enough to attempt inside the first fifteen seconds.
What should the reveal actually do?
The sample reveals in three ways. The most common holds the answer back by failing first: a wrong tap, a fail stamp, an exaggerated reaction, then the same question rephrased, which sustains watch time on correction urge. The second delivers the reveal as a joke rather than a solution, so the answer is remembered as a punchline. The third flashes all remaining answers at once and cuts to a title card. In every case the correct answer arrives late, never in the opening, and the close keeps the question loop open with a quantity promise such as new levels daily instead of ending it with a single download line.
What should a team hold fixed while testing?
Hold the question form, then the option count and layout, then the reveal timing, and change one at a time. The sample favours three answer options with a high-contrast outline on the candidate, and a reveal placed after the 20-second mark, with the fail-first beat treated as a default rather than an option. Because impressions and active days are lifetime values, the test should be read on its own measurement window rather than against the cumulative numbers quoted here.
What should teams check before copying this format?
First, check whether the shot description is complete: several rows return partial shot lists, and an unreturned segment is not evidence that no CTA exists. Second, check the field caliber: cumulative impressions and active days are lifetime values, so no in-window growth can be read from them. Third, note that image-format candidates in this dimension returned no visual description, so the static side of this format is under-covered rather than absent.
Not sure whether a question-style opener fits your puzzle or deduction game?
Get a free benchmark check based on your specific app or game category.
The durable part of this format is the gap between question and answer. Teams that copy only the question get a curious viewer; teams that copy the question, the option set and the delay get a viewer who stays to settle a bet they made themselves.